Result in contextOrdinary-split aggregate R² was 0.622 for AlCu and 0.604 for WTi. Keeping identical target profiles together changed those scores to 0.543 and 0.690. The change was large enough that I report both splits.
Context and questions
Infineon’s public release contains anonymized physical vapor deposition (PVD) process inputs and 17 target measurements for each of two metal-layer processes, AlCu and WTi.
I used the process inputs in two ways: to flag unusual runs for review and to predict the target measurements. A statistical alert and a prediction error answer different questions, so I kept those analyses separate.
| Process | Rows | Input columns | Targets |
|---|---|---|---|
| AlCu | 4,848 | 97 | 17 |
| WTi | 1,740 | 108 | 17 |
The release omits physical units, inverse scaling, timestamps, equipment identifiers, specifications, and fault labels. Those omissions limit how I can interpret the results.
My contribution
I wrote the Python workflow from the initial data audit through held-out evaluation. AlCu was the primary analysis. I then fitted the workflow separately on WTi to check how it behaved on the second process.
Data checks and decisions
I first checked the four CSV files against the published checksums. The audit found no missing or nonfinite values, and I checked duplicates and input/target row counts before modeling. There is no join key; the inputs and targets are paired by row position.
Each process also has one all-zero target record. I could not tell what it meant. I kept it in input-based monitoring but excluded it from primary target modeling, then checked its influence separately. Feature screening on the training data removed two near-constant AlCu channels.
Two analysis paths
Process-state monitoring
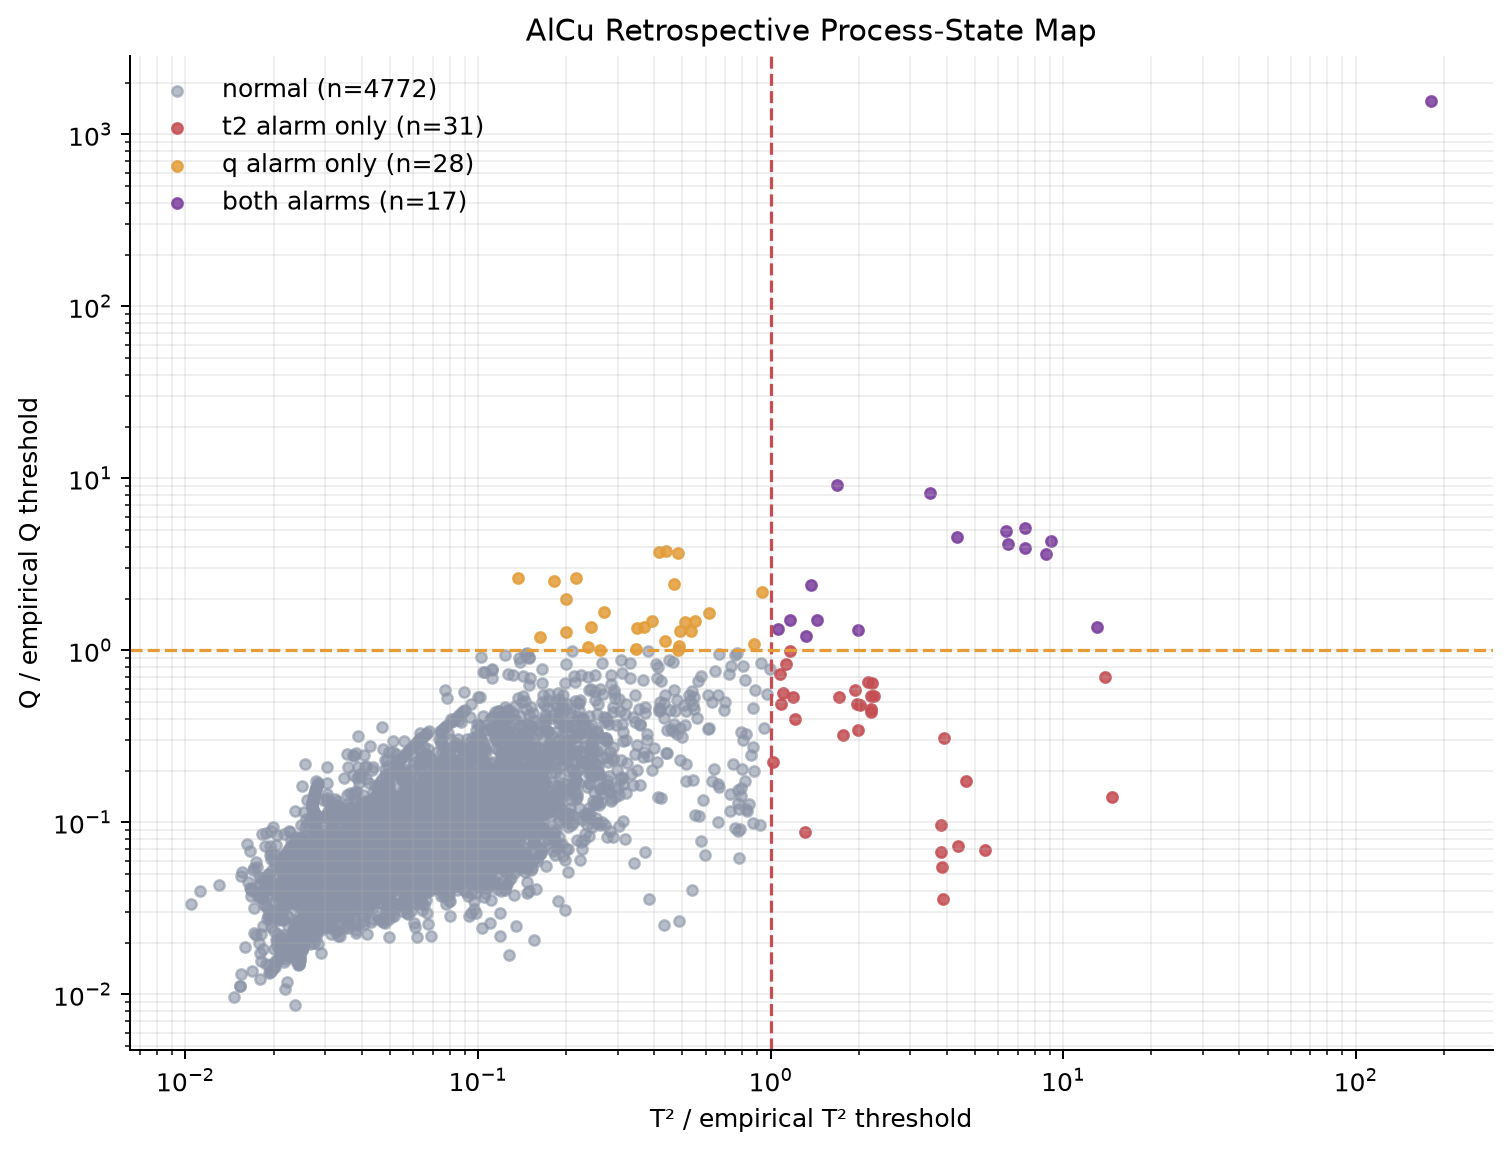
I fitted standardization and principal component analysis (PCA) on training rows only, retaining the fewest components needed to explain at least 90% of input variance: 34 for AlCu and 35 for WTi.
Hotelling T² measures distance within the retained PCA space; Q/SPE measures variation the model does not reconstruct. I used training-set 99th-percentile thresholds to flag statistical excursions and contribution analysis to identify anonymous channels for review.

17-target virtual metrology
I predicted all 17 released targets directly. Linear Regression and Ridge provided baselines. A fixed Random Forest was retained after a predeclared training-only improvement check. Its configuration transferred from the primary AlCu analysis to WTi, where the model was fitted again using WTi training data.
Held-out evaluation and profile grouping
The primary evaluation used a fixed 80/20 random split. Scaling, PCA fitting, model selection, and tuning used training data rather than held-out outcomes.
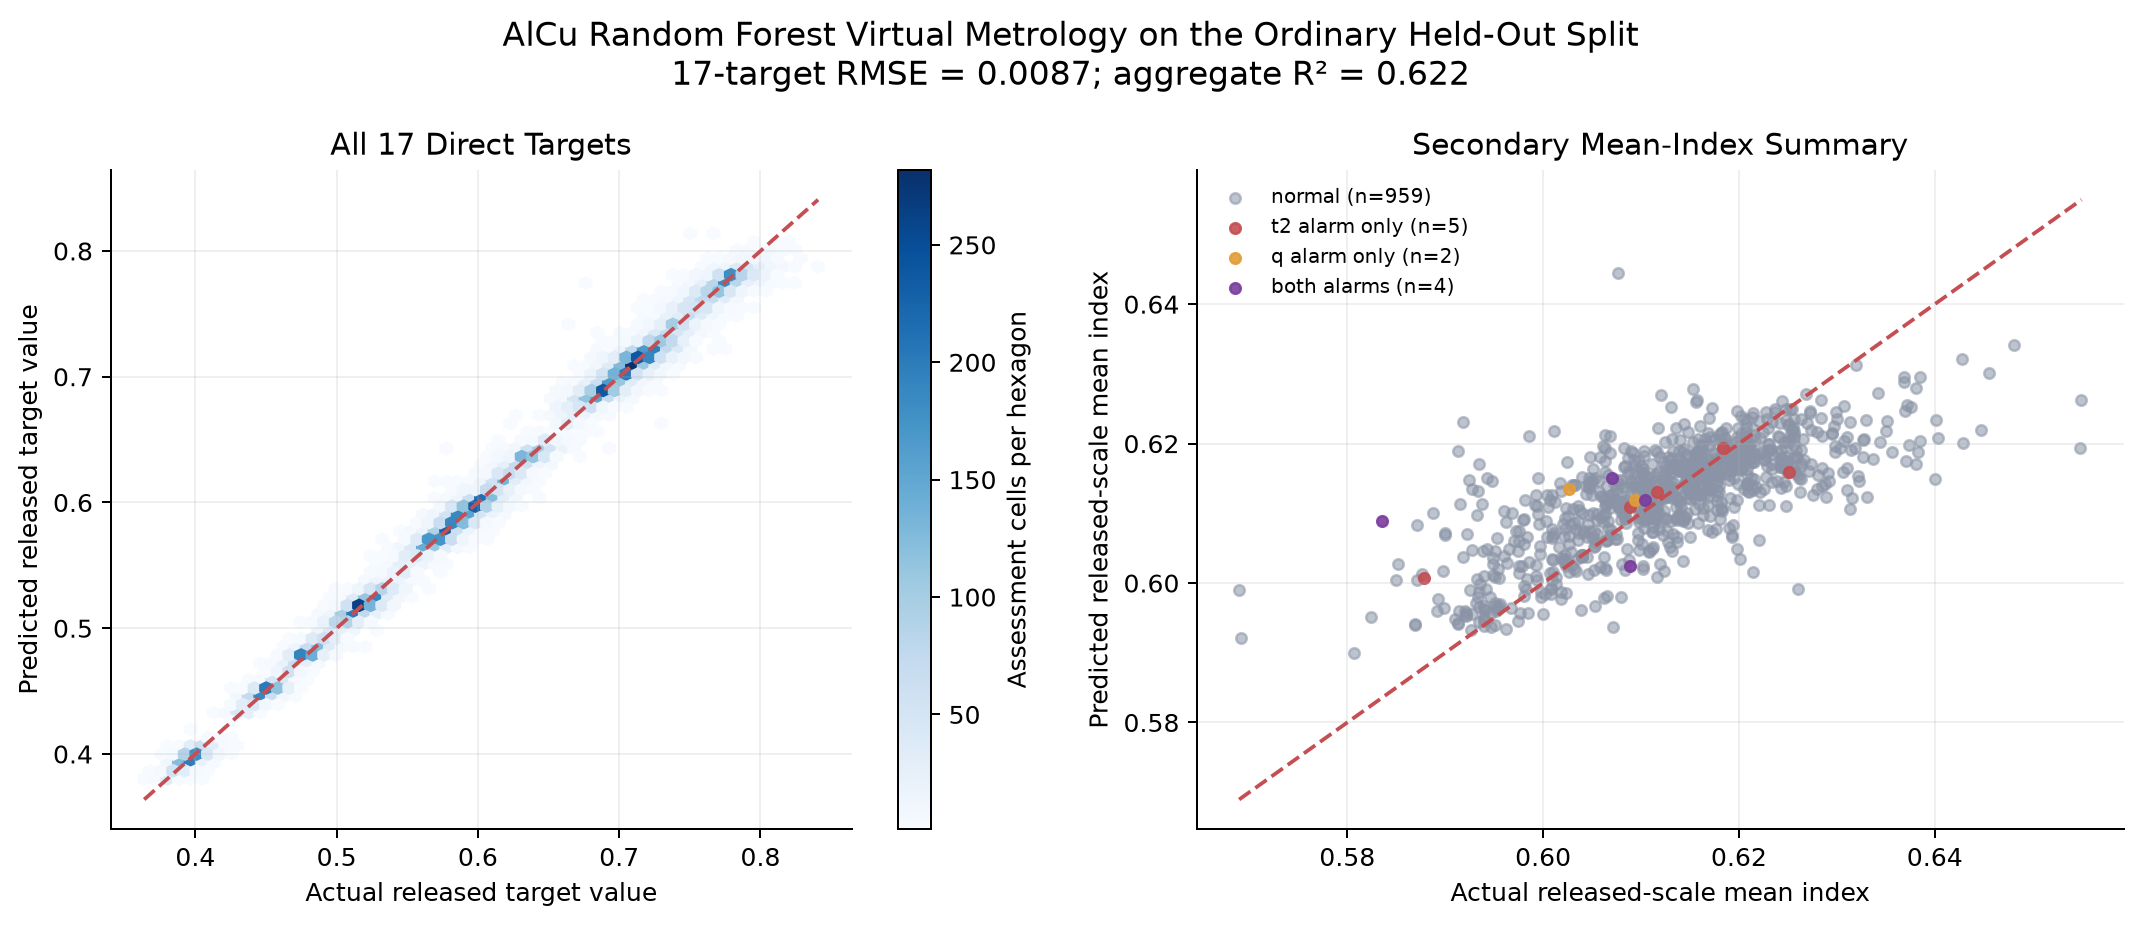

Some rows have exactly equal 17-target profiles. I repeated the evaluation with each identical-profile group kept entirely on one side of the split. I wanted to check whether profile repetition was making the ordinary split look better. Equal target profiles alone do not tell me that the rows are duplicate wafers. The grouped AlCu analysis used its own training-only model gate.
| Metric | AlCu | WTi |
|---|---|---|
| Ordinary-split aggregate R² | 0.622 | 0.604 |
| Grouped-profile aggregate R² | 0.543 | 0.690 |
| Ordinary-split RMSE | 0.00870 | 0.00829 |
| Grouped-profile RMSE | 0.00926 | 0.00767 |
Grouping increased AlCu RMSE by 6.4%, indicating some optimism in its ordinary-split result. WTi improved under grouping. Neither split establishes performance on future production runs: the release has no chronology for a time-based test.
Findings and engineering limits
The Random Forest retained predictive signal under both split designs. Monitoring flagged runs and ranked channels for review. However, comparisons between flagged and unflagged runs showed no clear shift in the released output summaries: the clustered 95% intervals included zero.
The thresholds flag statistical departures. With anonymous channels and no fault labels, I cannot use them to name a physical failure or its cause. The dataset also lacks a known-good time period and specifications, so it cannot support chronological SPC qualification or Cp/Cpk.
The prediction errors have a similar limit. Without units and inverse scaling, I cannot turn them into film-thickness tolerances or use them to rank AlCu and WTi physically. WTi provides a second dataset for the workflow; it is not an external fab qualification.
Artifacts and sources
The repository contains the numbered analysis scripts and reproduction instructions. The technical report and results guide include figures, per-target errors, and sensitivity tables.
Dataset: Amina Mević, Andreas Laber, and Senka Krivić, Advanced Process Control and Statistical Process Control Data for Thickness Prediction of AlCu and WTi Metal Layer in Semiconductor Manufacturing, licensed under CC BY 4.0. This page summarizes my public v1.0 project documentation, reviewed September 10, 2026.